
What is Crawlee?
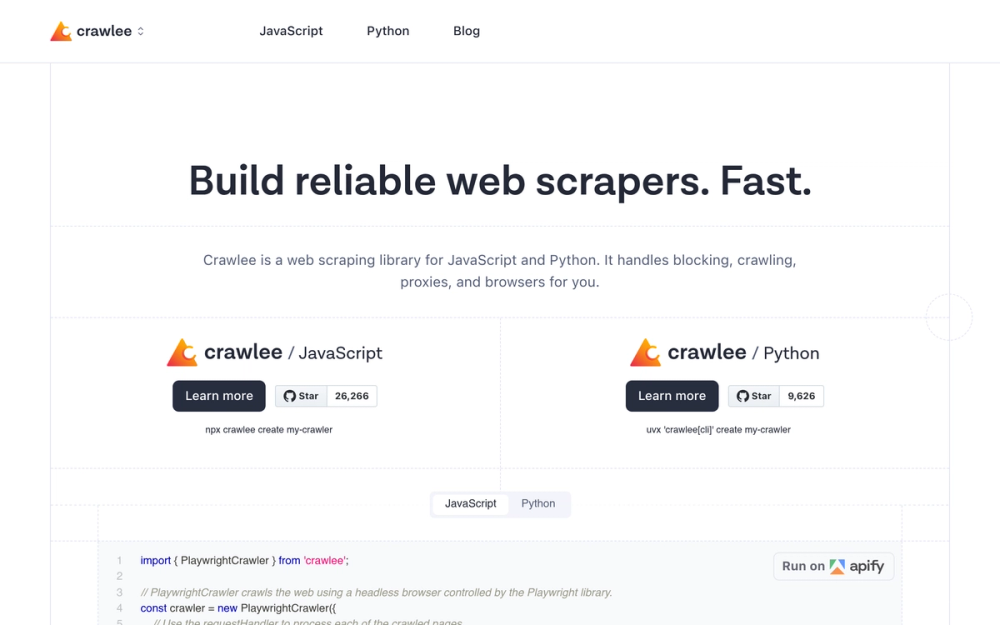
Crawlee is a web scraping and crawling library for JavaScript and Python that handles blocking, crawling, proxies, and browsers so developers can build reliable crawlers faster. Crawlee is free, open-source, and built by Apify, and it provides ready-made crawler classes such as PlaywrightCrawler that manage headless browser control, request queues, and data storage.
Key Features
- JavaScript and Python support: Crawlee is available as a library for both JavaScript and Python, with matching CLI scaffolding commands (
npx crawlee create my-crawlerfor JavaScript anduvx 'crawlee[cli]' create my-crawlerfor Python). - Built-in blocking and proxy handling: Crawlee handles blocking, crawling, proxies, and browsers for the developer, removing the need to wire these concerns together manually.
- Browser-controlled crawling with Playwright: The PlaywrightCrawler class crawls the web using a headless browser controlled by the Playwright library, giving crawlers access to rendered pages.
- Request handler model: Each crawled page is processed through an async requestHandler that receives the request, page, enqueueLinks, pushData, and log utilities, keeping crawl logic organized per page.
- Automatic link discovery: The enqueueLinks helper extracts links from the current page and adds them to the crawling queue, enabling multi-page crawls without manual queue management.
- Dataset storage and export: Results pushed with pushData are saved as JSON to the
./storage/datasets/defaultdirectory, and the full dataset can be exported to a single file such as./result.csvor accessed directly in code via getData. - Crawl limits and headless control: Options such as maxRequestsPerCrawl cap the number of requests in a crawl, and the headless option can be disabled to display the browser window during development.
- CLI templates: A command-line interface lets developers start a new crawler from a template rather than from a blank project.
Use Cases
- JavaScript developers building scrapers: A developer can scaffold a project with
npx crawlee create my-crawlerand use PlaywrightCrawler to crawl pages, log page titles, and store extracted data without assembling browser and queue infrastructure. - Python developers building scrapers: Python teams can scaffold with
uvx 'crawlee[cli]' create my-crawlerand use the same crawling, proxy, and blocking handling from Python. - Sites that require a real browser: Projects that need rendered pages can rely on PlaywrightCrawler's headless browser control, with the option to show the browser window while debugging.
- Multi-page data collection: Crawls that need to follow links across a site can use enqueueLinks to grow the request queue automatically and pushData to collect structured records as JSON.
- Dataset export workflows: Teams that need crawl output in a portable format can export the collected dataset to a single CSV file or work with the data directly in code.
Who It Is For
Crawlee is aimed at JavaScript and Python developers who need to build web scrapers and crawlers and would rather not implement browser control, request queuing, proxy handling, and blocking avoidance themselves. It suits developers who want a maintained open-source library behind their scraping projects, from small template-started crawlers to multi-page crawls that collect and export structured data.
Pricing
Crawlee is forever free and open-source. The source material does not list any paid tiers or pricing figures.
Frequently Asked Questions
What is Crawlee used for?
Crawlee is a web scraping library for JavaScript and Python used to build reliable crawlers. Crawlee handles blocking, crawling, proxies, and browsers, and provides crawler classes such as PlaywrightCrawler plus helpers for enqueueing links and storing extracted data.
Is Crawlee free?
Yes. Crawlee is described as forever free and open-source, and it is built by Apify.
Which languages does Crawlee support?
Crawlee is available for both JavaScript and Python. Each language has its own CLI command for creating a new crawler project from a template.
Does Crawlee work with Playwright?
Yes. Crawlee's PlaywrightCrawler crawls the web using a headless browser controlled by the Playwright library, and the headless option can be disabled to see the browser window.
How does Crawlee store scraped data?
Crawlee saves results pushed with pushData as JSON in the ./storage/datasets/default directory. The full dataset can be exported to a single file such as ./result.csv or read directly in code with getData.