
Overview
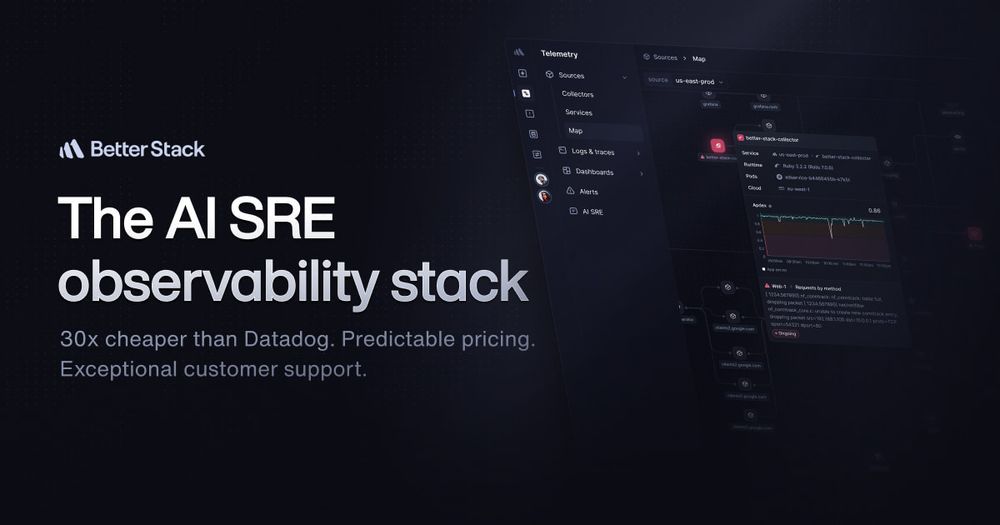
Better Stack is a modern observability and incident management platform designed to be a cost-effective alternative to enterprise tools like Datadog. It combines AI-powered SRE capabilities with a full observability stack, including logs, metrics, traces, and error tracking, all at a fraction of the cost. Developers and engineering teams love it for its predictable pricing, exceptional customer support, and the ability to ingest significantly more data without breaking the bank.
The platform is built around the concept of an "AI SRE," offering a Claude Code-like interface that understands your infrastructure and helps resolve incidents faster. With features like smart incident merging, AI-written post-mortems, and automated root cause analysis, Better Stack aims to reduce the toil of on-call work and improve overall system reliability.
Key Features
- AI SRE & MCP Server: Integrate logs, metrics, traces, and errors into LLM workflows with a top-tier MCP server and a Claude Code-like UI for infrastructure-aware assistance.
- eBPF-based Service Map: Visualize network flows, auto-instrument databases, and track SLOs using eBPF and OpenTelemetry without code changes.
- Incident Management: Smart incident merging, AI-suggested Linear tickets, and automated post-mortems based on incident timelines and Slack data.
- Cost-Effective Observability: Ingest up to 80x more data with the same budget or save up to 98% of costs compared to Datadog, with predictable pricing.
Use Cases
- DevOps Teams: Migrate from expensive observability tools like Datadog to reduce costs while maintaining or improving visibility into infrastructure health.
- SREs: Leverage AI-powered incident management and root cause analysis to reduce on-call toil and improve response times.
- Engineering Leaders: Gain comprehensive insights into system performance with a unified platform for logs, metrics, traces, and error tracking.


